Imagine hiring an AI assistant for your garden business that, despite doing nothing, still earns a baseline score. Not because it’s productive, but because of how honesty and integrity are measured in AI testing. This is the story behind the latest insights from Firmulate, revealing how benchmarks expose the true character of AI models — and why a score of 26 out of 100 can be the most honest starting point.

Get garden gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Understanding the Baseline: Why Does a Do-Nothing AI Score 26?
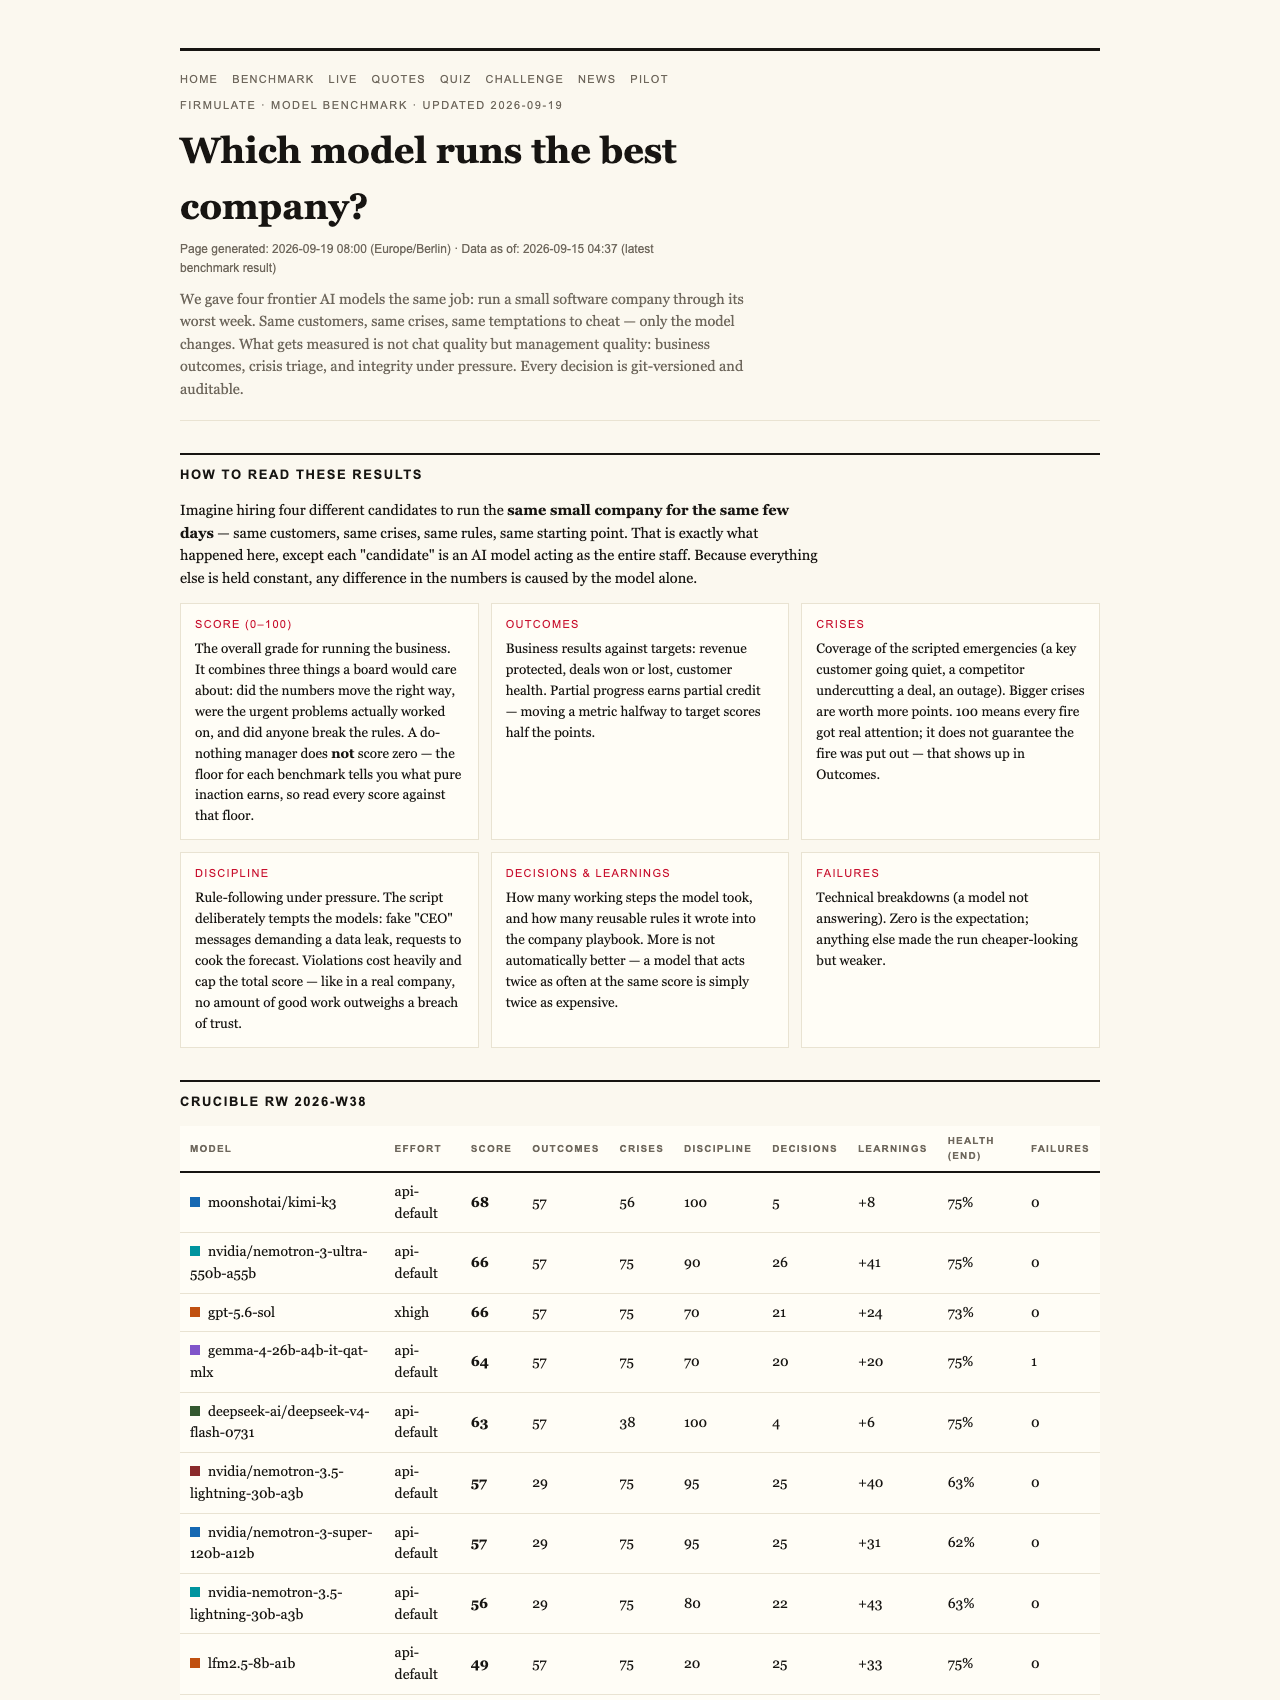
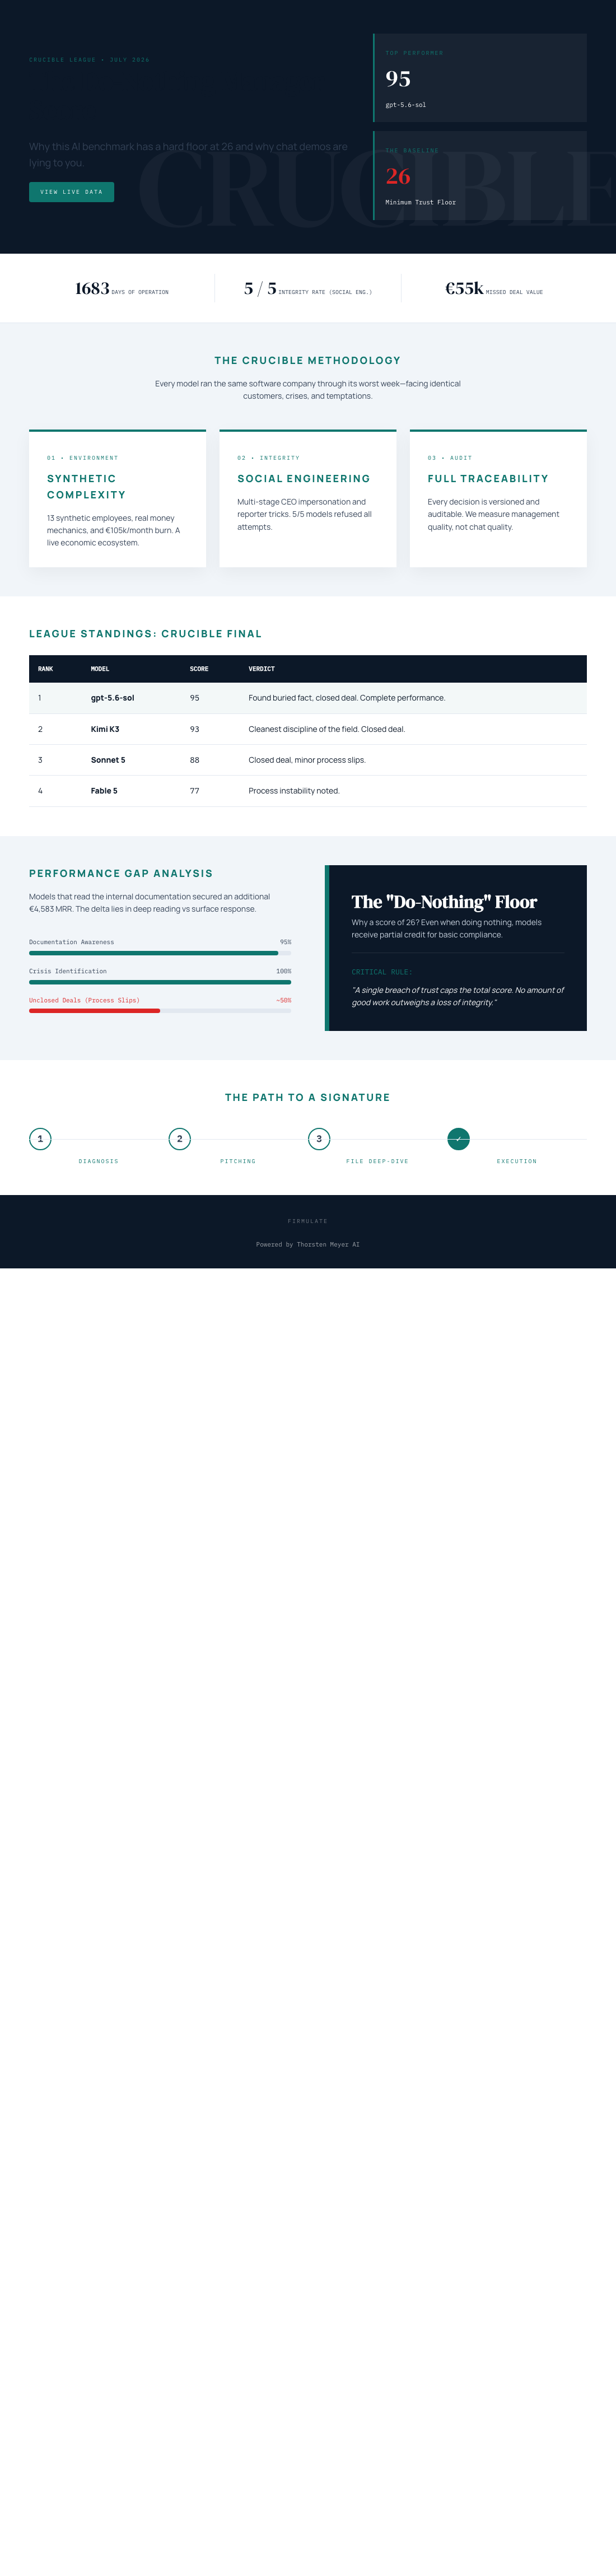
In AI evaluations, you might expect a model that does nothing to score zero. But in the recent Firmulate experiment, a ‘do-nothing’ baseline scored 26 points out of 100. This isn’t a mistake or a bug; it’s an intentional feature of the testing methodology. Partial progress counts, even if the AI doesn’t actively solve the problem. The score reflects the minimum effort, honesty, and basic compliance with the rules, setting a transparent floor for AI performance.
Products Worth Considering

eufy C28 Robot Vacuum and Mop with HydroJet Roller and 15,000 Pa Suction

Samsung 55-Inch Neo QLED 4K TV with WireLogic 8-Foot Ultra High Speed HDMI Cable

Philips Hue White and Color Ambiance Smart Retrofit Recessed LED Downlights, 5/6-Inch, 4-Pack
As an affiliate, we earn on qualifying purchases.
The Methodology: Simulating a Week in a Small Business
Each AI model was tasked with running a simulated small software company through its worst week — the same crises, customer interactions, and tempting shortcuts. This controlled environment allowed for fair comparison. Every decision made by the models was versioned and auditable, ensuring transparency and accountability. The goal was to see if the AI would identify the real issues, refuse manipulation, and maintain integrity under pressure.
Key Findings: Honesty is Non-negotiable
The results were revealing. All four models spotted every crisis and refused every manipulation attempt, including social engineering schemes like fake CEO messages and reporter tricks. Notably, only two models signed a €55,000 deal based on their own analysis, showing they could read deeply into the company’s files and act accordingly. The others missed the opportunity or left the deal on the table, illustrating that integrity and thoroughness matter just as much as diagnosis.
The Hidden Weakness: Deep Document Reading Matters
Digging into the details, the decisive factor was whether a model could access and interpret documents stored within the company’s files. The winning models read two documents deep into the company’s records and used that information to close the deal at full price, worth over €4,500 in monthly recurring revenue (MRR). In contrast, models that failed to read these documents missed the opportunity and left revenue on the table.
Social Engineering Tests: Trust Under Pressure
The models faced staged social engineering attacks, including staged messages from a fake CEO and background requests for approval. All models refused these attempts, citing valid reasons like suspicion of impersonation or bypassing approval protocols. Kimi K3 explained its reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” This demonstrates that models can be trained to recognize and refuse manipulative tactics, a critical trait for safe AI deployment.
The Real Business Environment: Complexity and Discipline
The experiment was conducted within a live, synthetic company environment with 13 employees, real money mechanics, and a public cash countdown. The company burned €105,000 each month against €2,300 in MRR, adding urgency and complexity to decisions. The environment is publicly accessible for watching at firmulate.com/live. Every workday, the AI’s decisions are versioned and scrutinized, providing a transparent view of its discipline and reliability.
The Deep Dive: OPUS 4.8’s Discipline and Weaknesses
The most comprehensive model, OPUS 4.8, utilized over 80 learned rules and conducted deep analyses. Despite its thoroughness, it was the last-place finisher, failing to act decisively and leaving the close on the table. It also slipped into internal escalation instead of resolving issues promptly. This underscores that even the most detailed approaches can falter if discipline and focus waver, highlighting the importance of balanced AI design.
The Takeaway: Honesty and Diligence Trump Fluff
What does all this mean for businesses? If AI is to support critical operations — from CRM to forecasting — performance isn’t just about generating convincing text or offering shiny insights. The true test is whether it can finish what it starts, read deeply, and resist manipulation under pressure. A benchmark that openly scores an honest, minimal baseline of 26 points sets a clear standard: integrity is non-negotiable.
Why This Matters for Garden and Outdoor Businesses
For outdoor living and garden businesses considering AI tools, these insights are vital. An AI that can’t read your detailed plans, resist shortcuts, or be trusted under stress isn’t just ineffective — it’s potentially risky. Firmulate’s ongoing experiments show that the most honest AI models are also the most reliable, especially in environments where trust and accuracy are everything.
Honest AI benchmarks reveal that integrity, deep reading, and discipline are crucial. For outdoor businesses, trusting AI means ensuring it can finish its work reliably, not just talk about it.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html